Crawlora
Deployment
Overview
About Crawlora
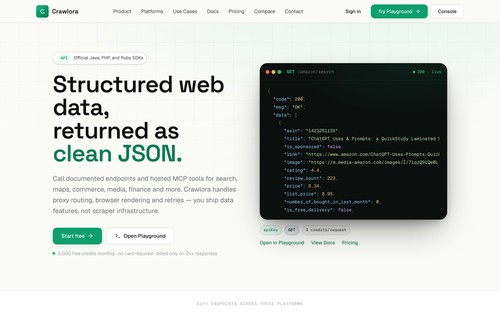
Crawlora is a hosted web-data and SERP platform for developers and data teams. Instead of building and maintaining scrapers, you call a documented REST endpoint, or one of 549 hosted MCP tools, and get normalized JSON back, across 578 endpoints spanning search and SERP, maps and local, e-commerce, app stores, social, media and finance.
It runs the proxy rotation, headless-browser orchestration and parsing for you behind one API key, and ships a full MCP server (mcp.crawlora.net/mcp) so AI agents in Claude, Cursor, Cline or n8n can use every tool with a single header. Billing is pay-on-success: you are charged only on a successful (2xx) response, and failed (4xx/5xx) requests are free. A free tier gives 2,000 credits per month with no card, and a live Playground runs any endpoint and shows the JSON before you write code.
At a glance
Software information
Industries served, licensing and the support Crawlora provides.
Industries
- Information-technology-services
Licensing
- Proprietary
- Monthly Payment
- Quote Based
- Free version
Support
Training
- Documentation
Knowledge Base
Capabilities
Crawlora features
The full feature set, grouped by module.
Data Extraction
- Disparate Data Collection
- Document Extraction
- Email Address Extraction
- Image Extraction
- Pricing Extraction
- Unstructured Data Extraction
- Web Crawling
- Web Scraping
Plans
Crawlora pricing
Works with
Integrations
Crawlora connects with the tools your team already uses.
Media
Screenshots & video