Key takeaways
- Most ML projects stall at deployment, long after the modeling work looks finished.
- A good checklist covers data, packaging, pipeline, release method, scaling, monitoring, security, and rollback.
- Models lose accuracy as live data changes, so monitoring has to start on launch day.
- Managed platforms save effort, but someone still has to make the architecture and cost decisions.
- If your team has no MLOps experience, a vetted partner can speed up delivery and save months of hiring time.
Companies are putting real money behind AI. In a recent AI adoption survey of 343 business leaders across 30 countries, 92.2% said they increased AI investment in 2026, and 59.3% called it a significant jump. Another 48.3% said AI is already deployed across multiple functions, while 35.0% said it is embedded organization-wide.
Spending is clearly rising. Getting a model to run reliably in production is a separate challenge, and it decides whether that spend pays off. Plenty of teams build a model that tests well, then struggle when real users and real data arrive. Machine learning model deployment best practices close that gap. This guide covers the checklist, the tools, and the point where outside help starts to make sense.
Already have a model stuck before launch? Compare machine learning companies that have taken models live, with verified reviews, ratings, and project history.
What is Machine Learning Model Deployment?
The term gets used in different ways, so it helps to pin it down first.
Machine learning model deployment is the step where a trained model leaves the notebook and starts making predictions inside a real product, app, or business process. The simple answer is that it makes a model usable by people other than the one who built it. Good machine learning deployment covers packaging the model, hosting it, releasing it, connecting it to live data, and watching its results afterward.
Many teams treat it as a final handoff. It works better as a second project, with its own skills, tools, and risks. That is also why model deployment in machine learning is a question worth answering early, before the budget and timeline are set.
Where a Model Can Run
The environment you choose affects cost, speed, and how much control you keep.
|
Deployment Environment |
How It Works |
Best For |
|---|---|---|
|
Local |
Model runs on one machine, like a laptop or an on-premises server |
Testing, offline work, and strict data residency rules |
|
Cloud |
Model runs on infrastructure that scales with demand |
Most production systems with changing traffic |
|
Edge |
Model runs on a device near the user, like a phone, camera, or sensor |
Low-latency needs and limited connectivity |
The environment you choose affects cost, speed, and how much control you keep. There are three common options.
- Local means the model runs on one machine, like a laptop or an on-premises server. It works well for testing, offline work, and strict data residency rules.
- Cloud means the model runs on infrastructure that scales with demand. Most production systems use it, especially when traffic changes throughout the day.
- Edge means the model runs on a device near the user, like a phone, camera, or sensor. It suits low-latency needs and places with limited connectivity.
What is Local Deployment in Machine Learning?
Local deployment means the model runs on a single machine that you control. That could be a developer's laptop, an office server, or a machine inside a factory. The model sits next to the data, and nothing has to travel over the internet.
Teams choose this setup for a few good reasons. It is quick to start, it costs little, and it keeps sensitive data on site, which matters in industries with strict privacy rules. It also works when there is no reliable connection.
The limit is scale. One machine can only handle so many requests at a time, and if it goes down, the model goes down with it. Once more than a small group needs predictions, most teams move to cloud deployment.
Batch and Real-Time Inference
Batch inference scores a large set of records on a schedule. Think nightly demand forecasts or a weekly list of customers likely to leave. Real-time inference answers a single request the moment it arrives, like a fraud check while someone is paying.
Real-time costs more to run and needs closer monitoring. If nobody is waiting for the answer, the batch is usually cheaper and easier to manage.
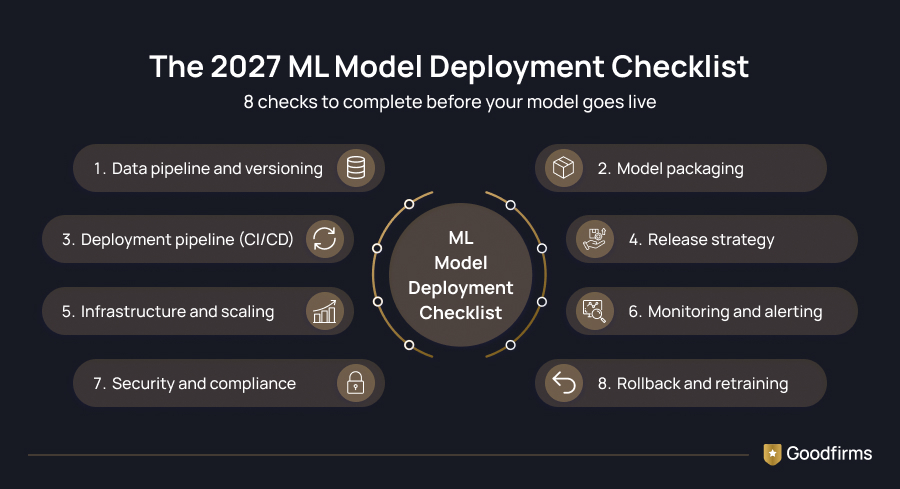
Machine Learning Model Deployment Best Practices: The 2027 Checklist
Go through this section carefully. If you are figuring out how to deploy machine learning models in production, work through these eight items in order. Each one removes a risk that normally shows up after launch. You can also use the list to score a vendor's proposal.
1. Data Pipeline Readiness and Versioning
A model is only as steady as the data feeding it. Clean and validate incoming data, and keep versions of both the training sets and the live feeds. When a prediction looks wrong, you should be able to trace it back to the exact data behind it.
Keep feature definitions identical in training and serving. A mismatch here is one of the most common reasons a model that tested well behaves oddly in production. Add automatic checks for missing values and impossible ranges, too.
If your data foundations are shaky, big data and analytics partners can help sort that out before you touch deployment.
2. Model Packaging and Reproducibility
Package the model in a container, pin your library versions, and store every release in a model registry. When something breaks, you can rebuild the exact version in minutes and compare it with the last one that worked.
3. The Machine Learning Deployment Pipeline
Manual releases are slow, and people make mistakes under pressure. A proper machine learning deployment pipeline moves a change from code to a live model automatically, much like CI/CD in regular software.
A solid pipeline runs tests on data, code, and model quality with every change. It pushes to staging first and asks a person to approve the final step. It also logs each release, so an audit takes minutes instead of days.
4. Release Strategy
Sending a new model to every user at once is a gamble. There are safer routes, and the right one depends on how much risk the business can take.
|
Release Strategy |
How It Works |
Best For |
|---|---|---|
|
Shadow |
New model runs quietly beside the old one, and outputs are compared |
You want zero user risk while testing |
|
Canary |
A small share of traffic goes to the new model, then grows |
You want an early warning with limited exposure |
|
Blue green |
Two identical environments, switch between them |
You need a fast switch back |
|
A/B test |
Two models compete on a live business metric |
You are judging the impact on conversions or revenue |
Most teams start with shadow or canary and move to A/B testing once the basics are stable.
5. Infrastructure and Scaling
Your model needs enough compute at the right moments, and no more. Size resources to real demand, set a latency target, and turn on autoscaling so a traffic spike does not take the service down.
Cloud costs creep up quietly. Idle instances, data transfer fees, and oversized endpoints add up faster than most teams expect, so read up on the hidden cloud computing costs before they show up on an invoice.
6. Monitoring, Alerting, and Performance Tracking
Track accuracy, latency, data quality, and drift on one dashboard. Send alerts to a named person, because a shared inbox nobody reads will not help at 2 AM.
Compare live predictions against actual outcomes whenever you can. That is the only reliable way to know the model still does its job. A model without monitoring is one you simply have to trust, and that is a risky habit.
7. Security, Access Control, and Compliance
Models touch valuable data, so they deserve the same protection as any critical system. Limit who can change or call them, keep audit trails, and encrypt sensitive data. Write down how decisions get made, since regulators and customers will eventually ask.
Some industries carry stricter rules than others. Looking at how healthcare AI companies and fintech AI companies handle privacy and compliance is a good way to see what a mature setup looks like.
8. Rollback and Retraining Plan
Decide in advance what counts as a rollback trigger, like a sharp drop in accuracy, and who has the authority to act on it. Set a retraining schedule and name the person responsible.
Why Most Machine Learning Projects Stall Before Production
Building a model and running a model are two different jobs. The first needs statistics and experimentation. The second needs reliability, security, and attention to operational detail. Teams that are strong at one have often not had to learn the other, and weak machine learning deployment habits show up quickly once users arrive.
That is why a successful pilot and a system that runs part of the business can be so far apart. Many companies celebrate the first demo, then spend months wondering why nothing has reached customers.
The Notebook Problem
In a notebook, you work with a clean sample of data, and you are the only user. In production, the data is messy, many people use the model at once, and it has to stay up all day. The code written for training also needs reworking before it can answer live requests.
Where Things Usually Go Wrong
A handful of problems account for most stalled launches:
- Data drift, where real-world inputs slowly change, and the model gets worse without anyone noticing
- No monitoring, so accuracy slips until a customer complains
- No rollback plan, which leaves a bad release live for days
- Unclear ownership, with data science and engineering each assuming the other side looks after the model
Why the Budget Takes the Hit
Each of those problems brings rework, delays, and surprise infrastructure bills. A team that budgets only for training often pays a second time to repair what went live. Planning for production from the start keeps those costs visible, and it makes the talk with finance a lot easier.
Machine Learning Deployment Tools and Platforms: What They Do and Where They Fall Short
Once the checklist makes sense, the next question is usually which tools to pick. There are plenty of machine learning deployment tools out there, so it helps to know what a platform actually takes off your plate.
Managed and Self-serve Options
Managed platforms such as Amazon SageMaker, Azure Machine Learning, and Google Vertex AI handle hosting, scaling, and updates for you. Open source tools like MLflow, Kubeflow, and BentoML give you more control, though your team runs and maintains the stack.
|
Deployment Approach |
Advantages |
Limitations |
|---|---|---|
|
Managed platforms |
Faster setup, less maintenance |
Higher cost at scale, some lock-in |
|
Open source tools |
Flexibility and control |
Needs experienced engineers |
Smaller teams usually start with a managed platform. Larger teams with custom needs often move toward open source over time, and many end up using a mix.
AWS Machine Learning Deployment in Practice
Since AWS machine learning deployment is one of the most searched topics in this space, here is how it usually goes. You package the model, pick an instance type, and deploy it behind a SageMaker endpoint. Autoscaling adjusts capacity as traffic changes, and built-in monitoring tracks latency and errors.
It is convenient, but costs climb quickly when endpoints run around the clock with little traffic. Check your usage regularly and shut down what you do not need.
1. What Platforms Handle for You
Most platforms offer autoscaling, health checks, and version swaps out of the box. That cuts a lot of manual effort and shortens release cycles. You still set the thresholds, write the alert rules, and decide the rollout order.
2. Where Human Expertise Still Matters
No platform fixes poor data, weak architecture, or runaway spending. Someone has to design the pipeline, tune the alerts, and question results that look off. Generative models add another layer, from prompt handling to output safety. If that is your next step, see how large language model companies approach production use.
Build In-House or Hire a Deployment Partner?
At some point, every team has this conversation. There is no universal answer, but a few direct questions usually point the way.
What to Weigh
Start with team maturity. Do you already have engineers who have run models in production? Then look at the timeline, because learning on the job takes longer than most plans allow. Think about risk, too. A failed launch costs very different amounts at a retailer and at a bank.
Budget matters as well. Hiring, tooling, and cloud usage all add up, and the AI consulting services guide lays out real pricing and engagement models if you want a benchmark.
Where Outside Help Pays Off
Pipelines, monitoring, and security are the usual gaps. These skills take months to hire for. Plenty of companies keep model building in-house and hand these parts to a partner. The core knowledge stays inside the team, and delivery speeds up.
Signs You Are Ready for a Partner
- Pilots keep stalling before they reach users
- Nobody on the team has MLOps experience
- A deadline is close, and the risk feels high
- Models already in production are drifting with nobody watching them
If two or more of those sound familiar, AI consulting companies are a sensible place to start the conversation.
Shortlisting a Partner
Look at verified client reviews, past projects, industry fit, and what happens after launch. Ask how they handle monitoring and rollback, because the answer says a lot about how mature they are. Comparing artificial intelligence companies side by side makes gaps in experience easy to spot. And a good match can last years, as this story of a long-term AI partnership shows.
Conclusion
Go back through the checklist and count how many of the eight items your team could tick off today. Zero to three means you have a clear starting point and some quick wins waiting. Four to six puts you closer than you probably thought. Seven or eight, and you are ready to launch with confidence.
Whatever your score, the pattern behind good machine learning model deployment best practices stays the same: prepare early, monitor constantly, and make sure someone owns the model after launch. Pick the weakest item on your list and fix it this week. Then send the checklist to a teammate and ask them to score it too. The gap between your answers will tell you plenty.
FAQs -Machine Learning Model Deployment
1. What is machine learning model deployment?
It is the process of moving a trained model into a live environment where it makes predictions for real users or systems. The work covers packaging, hosting, releasing, and monitoring. A model only creates business value once it is running reliably, which is why this step often decides whether an AI project pays off.
2. What is deployment in machine learning?
Deployment turns a working model into a working product. The model gets connected to live data and applications so people can use its output in daily decisions. It differs from training, which happens earlier in a controlled setting. Deployment brings real traffic and real consequences.
3. What is local deployment in machine learning?
Local deployment means running the model on a single machine, such as a laptop or on-premises server. It suits testing, offline use, and cases where data has to stay on site for privacy or legal reasons. The limit is scale, so teams usually move to the cloud once demand grows.
4. How to deploy machine learning models in production?
Prepare and version your data first, then package the model in a container. Automate releases through a pipeline and roll out gradually, with a canary release, for example, so only a small share of traffic is affected at the start. After launch, monitor accuracy, latency, and drift, and keep a rollback plan ready.
5. What are the best practices for machine learning model deployment?
Version your data and models, automate testing and releases, and roll out in stages. Monitor drift and accuracy continuously, secure access, and document decisions. Plan rollback and retraining before launch, and give the model a clear owner. Teams that follow these habits see far fewer production surprises.
6. Which tools are used for machine learning deployment?
Managed options include Amazon SageMaker, Azure Machine Learning, and Google Vertex AI. Open source choices include MLflow, Kubeflow, and BentoML. The right pick depends on team size, budget, and how much control you need. Smaller teams often begin with a managed platform and add open source tools later.